Calculate data to construct partial dependence plots for a given predictor
Usage
data_pdp(
  model,
  predictors,
  resolution = 50,
  resid = FALSE,
  training_data = NULL,
  projection_data = NULL,
  clamping = FALSE
)
Arguments
- model
A model object of class "gam", "gbm", "glm", "graf", "ksvm", "ksvm", "maxnet”, “nnet", and "randomForest" This model can be found in the first element of the list returned by any function from the fit_, tune_, or esm_ function families
- predictors
character. Vector with a predictor name.
- resolution
numeric. Number of equally spaced points at which to predict continuous predictors. Default 50
- resid
logical. Calculate residuals based on training data. Default FALSE
- training_data
data.frame. Database with response (0,1) and predictor values used to fit a model. Default NULL
- projection_data
SpatRaster. Raster layer with environmental variables used for model projection. When this argument is used, function will calculate partial dependence curves distinguishing conditions used in training and projection conditions (i.e., projection data present in projection area but not training). Default NULL
- clamping
logical. Perform clamping. Only for maxent models. Default FALSE
Value
A list with two tibbles "pdpdata" and "resid".
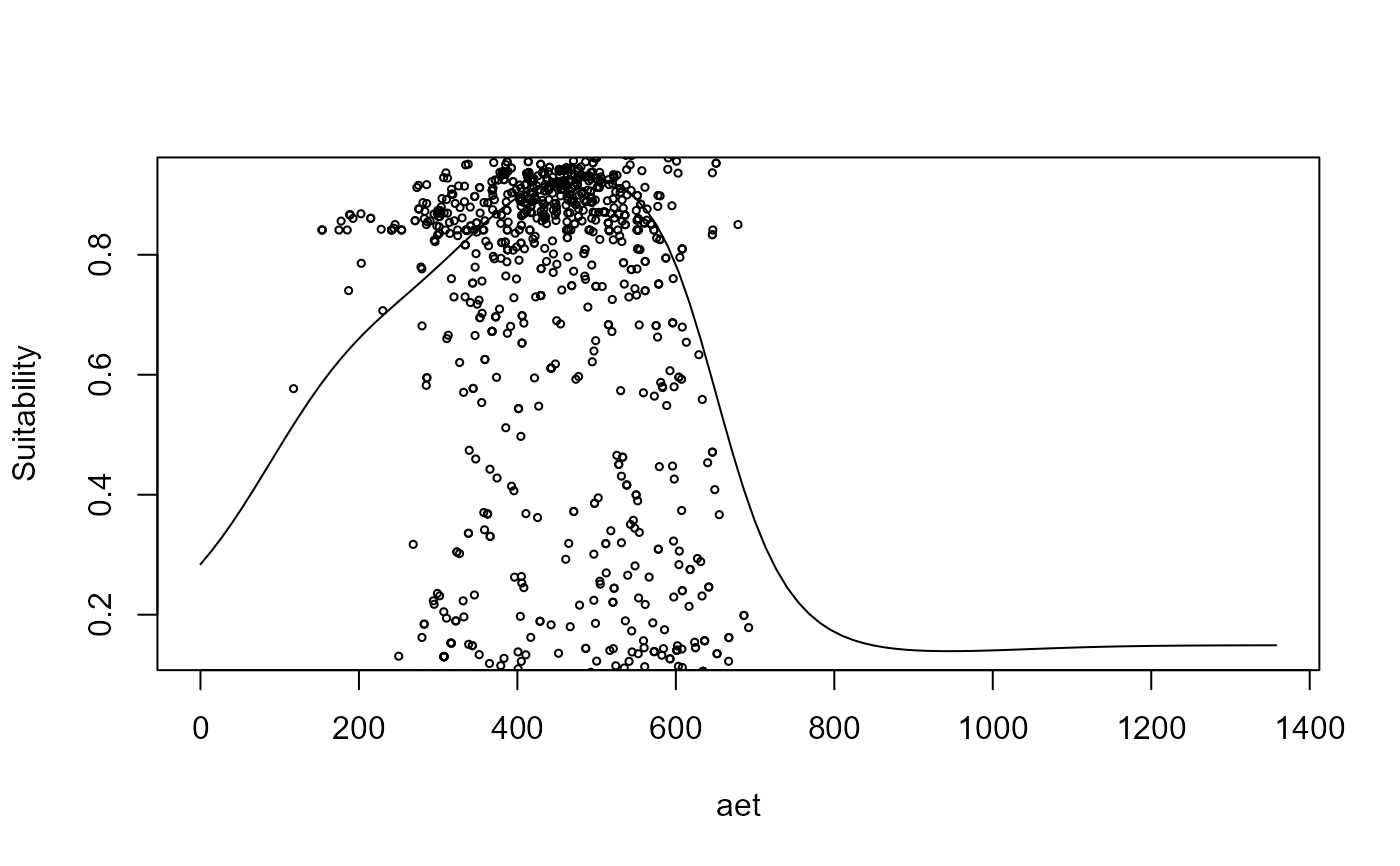
pdpdata: has data to construct partial dependence plots, the first column includes values of the selected environmental variable, the second column with predicted suitability, and the third column with range type, with two values Training and Projecting, referring to suitability calculated within and outside the range of training conditions. Third column is only returned if "projection_data" argument is used
resid: has data to plot residuals. The first column includes values of the selected environmental variable and the second column with predicted suitability.
Examples
# \donttest{
library(terra)
library(dplyr)
somevar <- system.file("external/somevar.tif", package = "flexsdm")
somevar <- terra::rast(somevar) # environmental data
names(somevar) <- c("aet", "cwd", "tmx", "tmn")
data(abies)
abies2 <- abies %>%
select(x, y, pr_ab)
abies2 <- sdm_extract(abies2,
x = "x",
y = "y",
env_layer = somevar
)
#> 60 rows were excluded from database because NAs were found
abies2 <- part_random(abies2,
pr_ab = "pr_ab",
method = c(method = "kfold", folds = 5)
)
svm_t1 <- fit_svm(
data = abies2,
response = "pr_ab",
predictors = c("aet", "cwd", "tmx", "tmn"),
partition = ".part",
thr = c("max_sens_spec")
)
#> Formula used for model fitting:
#> pr_ab ~ aet + cwd + tmx + tmn
#> Replica number: 1/1
#> Partition number: 1/5
#> Partition number: 2/5
#> Partition number: 3/5
#> Partition number: 4/5
#> Partition number: 5/5
df <- data_pdp(
model = svm_t1$model,
predictors = c("aet"),
resolution = 100,
resid = TRUE,
projection_data = somevar,
training_data = abies2,
clamping = FALSE
)
df
#> $pdpdata
#> # A tibble: 102 × 3
#> aet Suitability Type
#> <dbl> <dbl> <chr>
#> 1 0 0.284 Projection
#> 2 13.7 0.306 Projection
#> 3 27.4 0.330 Projection
#> 4 41.1 0.356 Projection
#> 5 54.9 0.383 Projection
#> 6 68.6 0.412 Projection
#> 7 82.3 0.441 Projection
#> 8 96.0 0.471 Projection
#> 9 110. 0.500 Projection
#> 10 117. 0.517 Training
#> # ℹ 92 more rows
#>
#> $resid
#> # A tibble: 1,340 × 2
#> aet Suitability
#> <dbl> <dbl>
#> 1 610. 0.00569
#> 2 781. 0.0483
#> 3 237. 0.0213
#> 4 949. 0.0915
#> 5 338. 0.336
#> 6 510. 0.0404
#> 7 309. 0.0986
#> 8 634. 0.106
#> 9 497. 0.0884
#> 10 261. 0.0884
#> # ℹ 1,330 more rows
#>
names(df)
#> [1] "pdpdata" "resid"
df$pdpdata
#> # A tibble: 102 × 3
#> aet Suitability Type
#> <dbl> <dbl> <chr>
#> 1 0 0.284 Projection
#> 2 13.7 0.306 Projection
#> 3 27.4 0.330 Projection
#> 4 41.1 0.356 Projection
#> 5 54.9 0.383 Projection
#> 6 68.6 0.412 Projection
#> 7 82.3 0.441 Projection
#> 8 96.0 0.471 Projection
#> 9 110. 0.500 Projection
#> 10 117. 0.517 Training
#> # ℹ 92 more rows
df$resid
#> # A tibble: 1,340 × 2
#> aet Suitability
#> <dbl> <dbl>
#> 1 610. 0.00569
#> 2 781. 0.0483
#> 3 237. 0.0213
#> 4 949. 0.0915
#> 5 338. 0.336
#> 6 510. 0.0404
#> 7 309. 0.0986
#> 8 634. 0.106
#> 9 497. 0.0884
#> 10 261. 0.0884
#> # ℹ 1,330 more rows
plot(df$pdpdata[1:2], type = "l")
points(df$resid[1:2], cex = 0.5)
 # see p_pdp to construct partial dependence plot with ggplot2
# }