This function explores spatial blocks with different cell sizes and returns the most suitable size for a given presence or presence-absence database. The selection of the best grid size is performed automatically considering spatial autocorrelation, environmental similarity, and the number of presence and absence records in each partition.
Usage
part_sblock(
  env_layer,
  data,
  x,
  y,
  pr_ab,
  n_part = 3,
  min_res_mult = 3,
  max_res_mult = 200,
  num_grids = 30,
  min_occ = 10,
  prop = 0.5
)
Arguments
- env_layer
SpatRaster. Raster with environmental variable. Used to evaluate spatial autocorrelation and environmental similarity between training and testing partitions. Because this function calculate dissimilarity based on Euclidean distances, it can only be used with continuous environmental variables
- data
data.frame. Data.frame or tibble object with presence (or presence-absence, or presences-pseudo-absence) records, and coordinates
- x
character. Column name with spatial x coordinates
- y
character. Column name with spatial y coordinates
- pr_ab
character. Column with presence, presence-absence, or pseudo-absence records. Presences must be represented by 1 and absences by 0
- n_part
integer. Number of partition. Default 2.
- min_res_mult
integer. Minimum value used for multiplying raster resolution and define the finest resolution to be tested, default 3.
- max_res_mult
integer. Maximum value used for multiplying raster resolution and define the coarsest resolution to be tested, default 200.
- num_grids
integer. Number of grid to be tested between min_res_mult X (raster resolution) and max_res_mult X (raster resolution), default 30
- min_occ
numeric. Minimum number of presences or absences in a partition fold. The min_occ value should be base on the amount of predictors in order to avoid over-fitting or error when fitting models for a given fold. Default 10.
- prop
numeric. Proportion of point used for testing autocorrelation between groups (values > 0 and <=1). The smaller this proportion is, the faster the function will work. Default 0.5
Value
A list with:
part: A tibble object with information used in 'data' arguments and a additional column .part with partition group.
best_part_info: A tibble with information about the best partition. It contains the number of the best partition (n_grid), cell size (cell_size), standard deviation of presences (sd_p), standard deviation of absences (sd_a), Moran's I spatial autocorrelation (spa_auto), and environmental similarity based on Euclidean distance (env_sim).
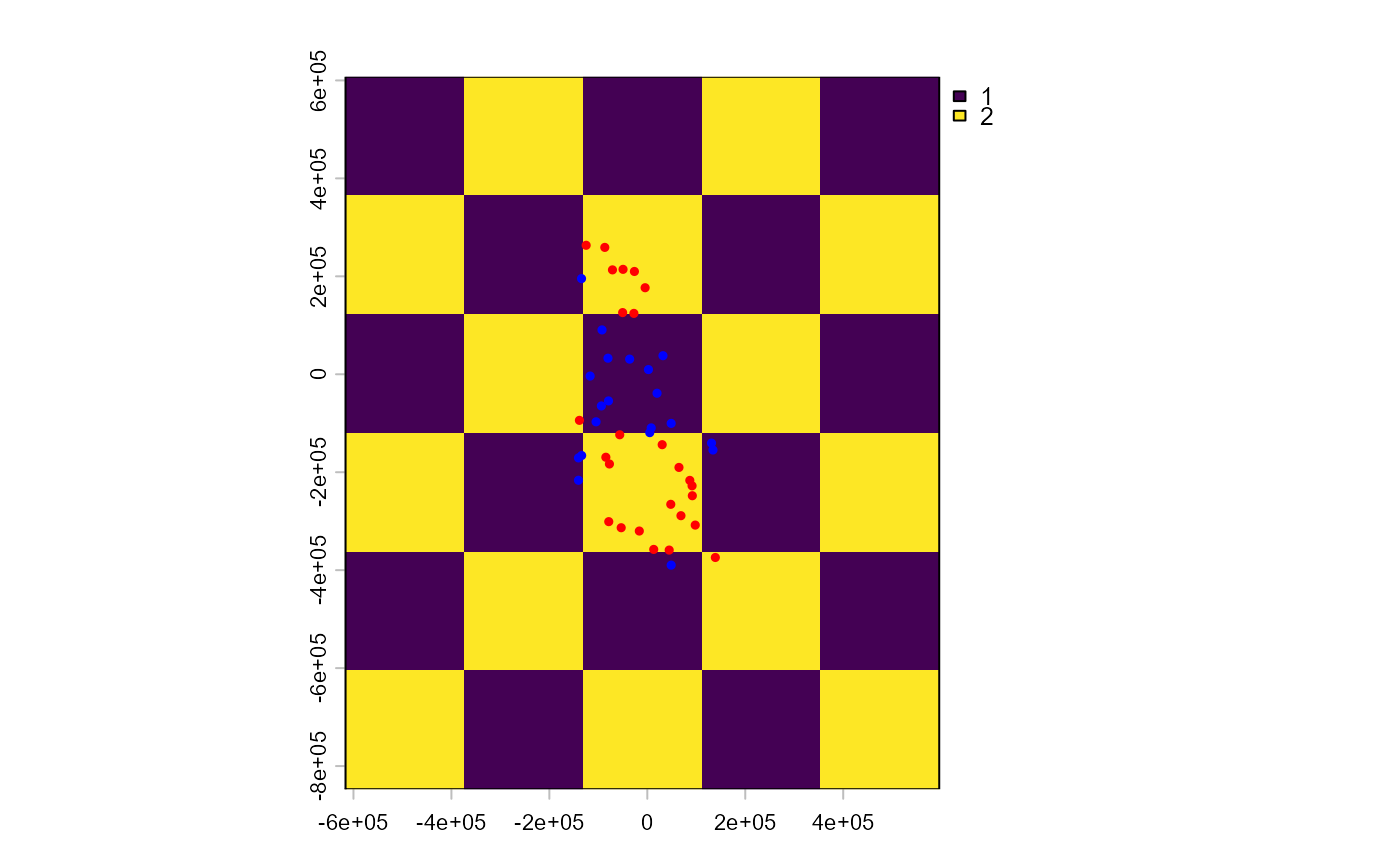
grid: A SpatRaster object with blocks
Details
The part_sblock allows test with different numbers of partitions using square blocks (like a checkerboard). This function explores a range of block sizes and automatically selects the best size for a given given presence, presence-absences, or presence-pseudo-absences dataset. Number of partition selection is based on an optimization procedure that explores partition size in three dimensions determined by spatial autocorrelation (measured by Moran's I), environmental similarity (Euclidean distance), and difference in the amount of data among partition groups (Standard Deviation - SD; Velazco et al., 2019). This procedure will iteratively select partitions, first those partitions with autocorrelation values less than the lowest quartile of Morans I, then those with environmental similarity values greater than the third quartile of the Euclidean distances than those with a difference in the amount of data less than the lowest quartile of SD. This selection is repeated until only one partition is retained (Velazco et al., 2019). The main benefit of this partition selection are that it i) is not subjective, ii) balances the environmental similarity and special autocorrelation between partitions, and iii) controls the selection of partitions with too few data that may be problematic for model fitting ("min_occ" argument).
Geographically structured partitions tend to evaluate model transferability more directly than
conventional ones (e.g., those performed by part_random) (Roberts et al., 2017;
Santini et al., 2021), and are relevant for models that are to be used for projections in other
regions outside the training area or for other time periods.
This function can interact with get_block, sample_background,
and sample_pseudoabs for sampling background points or pseudo-absences within
spatial partition groups
References
Roberts, D. R., Bahn, V., Ciuti, S., Boyce, M. S., Elith, J., Guillera-Arroita, G., Hauenstein, S., Lahoz-Monfort, J. J., Schroder, B., Thuiller, W., Warton, D. I., Wintle, B. A., Hartig, F., & Dormann, C. F. (2017). Cross-validation strategies for data with temporal, spatial, hierarchical, or phylogenetic structure. Ecography, 40, 913-929. https://doi.org/10.1111/ecog.02881
Santini, L., Benitez-Lopez, A., Maiorano, L., Cengic, M., & Huijbregts, M. A. J. (2021). Assessing the reliability of species distribution projections in climate change research. Diversity and Distributions, ddi.13252. https://doi.org/10.1111/ddi.13252
Velazco, S. J. E., Villalobos, F., Galvao, F., & De Marco Junior, P. (2019). A dark scenario for Cerrado plant species: Effects of future climate, land use and protected areas ineffectiveness. Diversity and Distributions, 25(4), 660-673. https://doi.org/10.1111/ddi.12886
See also
part_random, part_sband, part_senv,
get_block, and plot_res.
Examples
# \donttest{
require(terra)
require(dplyr)
# Load datasets
data(spp)
f <- system.file("external/somevar.tif", package = "flexsdm")
somevar <- terra::rast(f)
# Example for one single species
single_spp <- spp %>% dplyr::filter(species == "sp3")
part <- part_sblock(
env_layer = somevar,
data = single_spp,
x = "x",
y = "y",
pr_ab = "pr_ab",
min_res_mult = 10,
max_res_mult = 500,
num_grids = 30,
n_part = 2,
min_occ = 5,
prop = 0.5
)
#> 4 rows were excluded from database because NAs were found
#> The following grid cell sizes will be tested:
#> 18900 | 50834.48 | 82768.97 | 114703.45 | 146637.93 | 178572.41 | 210506.9 | 242441.38 | 274375.86 | 306310.34 | 338244.83 | 370179.31 | 402113.79 | 434048.28 | 465982.76 | 497917.24 | 529851.72 | 561786.21 | 593720.69 | 625655.17 | 657589.66 | 689524.14 | 721458.62 | 753393.1 | 785327.59 | 817262.07 | 849196.55 | 881131.03 | 913065.52 | 945000
#> Creating basic raster mask...
#> Searching for the optimal grid size...
part
#> $part
#> # A tibble: 46 × 4
#> x y pr_ab .part
#> <dbl> <dbl> <dbl> <int>
#> 1 -26331. 209912. 1 2
#> 2 -134331. 195332. 1 1
#> 3 68709. -288778. 0 2
#> 4 -79251. -54418. 0 1
#> 5 97869. -307948. 0 2
#> 6 4989. -119218. 0 1
#> 7 30369. -143788. 0 2
#> 8 91929. -248008. 0 2
#> 9 -80331. 32792. 0 1
#> 10 131079. -140548. 1 1
#> # ℹ 36 more rows
#>
#> $best_part_info
#> # A tibble: 1 × 6
#> n_grid cell_size spa_auto env_sim sd_p sd_a
#> <int> <dbl> <dbl> <dbl> <dbl> <dbl>
#> 1 4 242441. 0.126 354. 1.41 2.83
#>
#> $grid
#> class : SpatRaster
#> size : 6, 5, 1 (nrow, ncol, nlyr)
#> resolution : 242441.4, 242441.4 (x, y)
#> extent : -616127.2, 596079.7, -847254.7, 607393.6 (xmin, xmax, ymin, ymax)
#> coord. ref. : +proj=aea +lat_0=0 +lon_0=-120 +lat_1=34 +lat_2=40.5 +x_0=0 +y_0=-4000000 +datum=NAD83 +units=m +no_defs
#> source(s) : memory
#> name : .part
#> min value : 1
#> max value : 2
#>
part$part # database with partition fold (.part)
#> # A tibble: 46 × 4
#> x y pr_ab .part
#> <dbl> <dbl> <dbl> <int>
#> 1 -26331. 209912. 1 2
#> 2 -134331. 195332. 1 1
#> 3 68709. -288778. 0 2
#> 4 -79251. -54418. 0 1
#> 5 97869. -307948. 0 2
#> 6 4989. -119218. 0 1
#> 7 30369. -143788. 0 2
#> 8 91929. -248008. 0 2
#> 9 -80331. 32792. 0 1
#> 10 131079. -140548. 1 1
#> # ℹ 36 more rows
part$part %>%
group_by(pr_ab, .part) %>%
count() # number of presences and absences in each fold
#> # A tibble: 4 × 3
#> # Groups: pr_ab, .part [4]
#> pr_ab .part n
#> <dbl> <int> <int>
#> 1 0 1 15
#> 2 0 2 19
#> 3 1 1 5
#> 4 1 2 7
part$best_part_info # information of the best partition
#> # A tibble: 1 × 6
#> n_grid cell_size spa_auto env_sim sd_p sd_a
#> <int> <dbl> <dbl> <dbl> <dbl> <dbl>
#> 1 4 242441. 0.126 354. 1.41 2.83
part$grid # raster with folds
#> class : SpatRaster
#> size : 6, 5, 1 (nrow, ncol, nlyr)
#> resolution : 242441.4, 242441.4 (x, y)
#> extent : -616127.2, 596079.7, -847254.7, 607393.6 (xmin, xmax, ymin, ymax)
#> coord. ref. : +proj=aea +lat_0=0 +lon_0=-120 +lat_1=34 +lat_2=40.5 +x_0=0 +y_0=-4000000 +datum=NAD83 +units=m +no_defs
#> source(s) : memory
#> name : .part
#> min value : 1
#> max value : 2
# Explore the Grid object
plot(part$grid)
points(part$part[c("x", "y")],
col = c("blue", "red")[part$part$.part],
cex = 0.5,
pch = 19
)
 terra::res(part$grid)
#> [1] 242441.4 242441.4
terra::res(somevar)
#> [1] 1890 1890
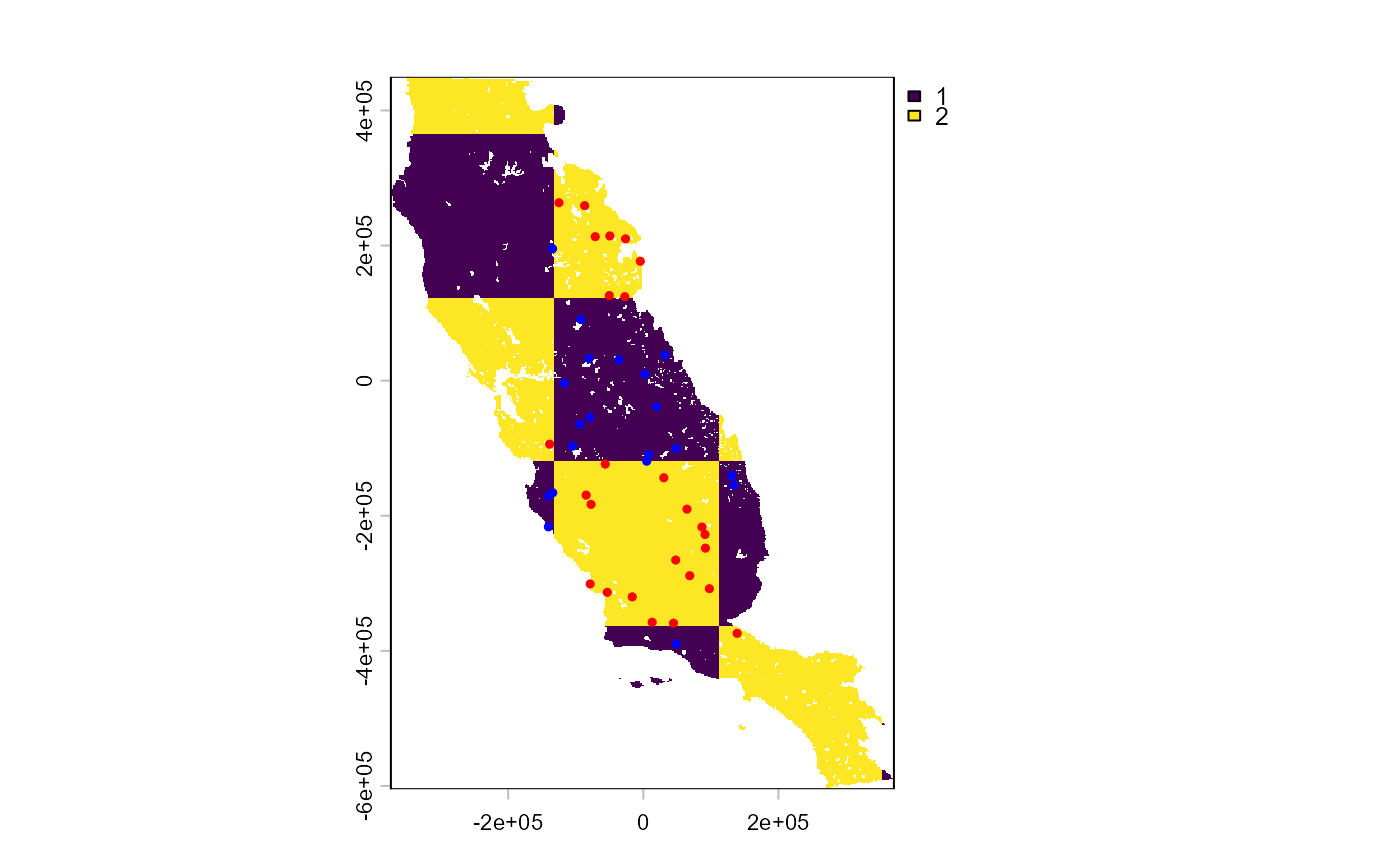
# Note that this is a layer with block partition, but it has a
# different resolution than the original environmental variables.
# If you wish have a layer with the same properties
# (i.e. resolution, extent, NAs) as your original environmental
# variables you can use the \code{\link{get_block}} function.
grid_env <- get_block(env_layer = somevar, best_grid = part$grid)
plot(grid_env) # this is a block layer with the same layer
# properties as environmental variables.
points(part$part[c("x", "y")],
col = c("blue", "red")[part$part$.part],
cex = 0.5,
pch = 19
)
 # This layer is very useful if you need to sample
# pseudo_absence or background point
# See examples in \code{\link{backgroudp}} and \code{\link{pseudoabs}}
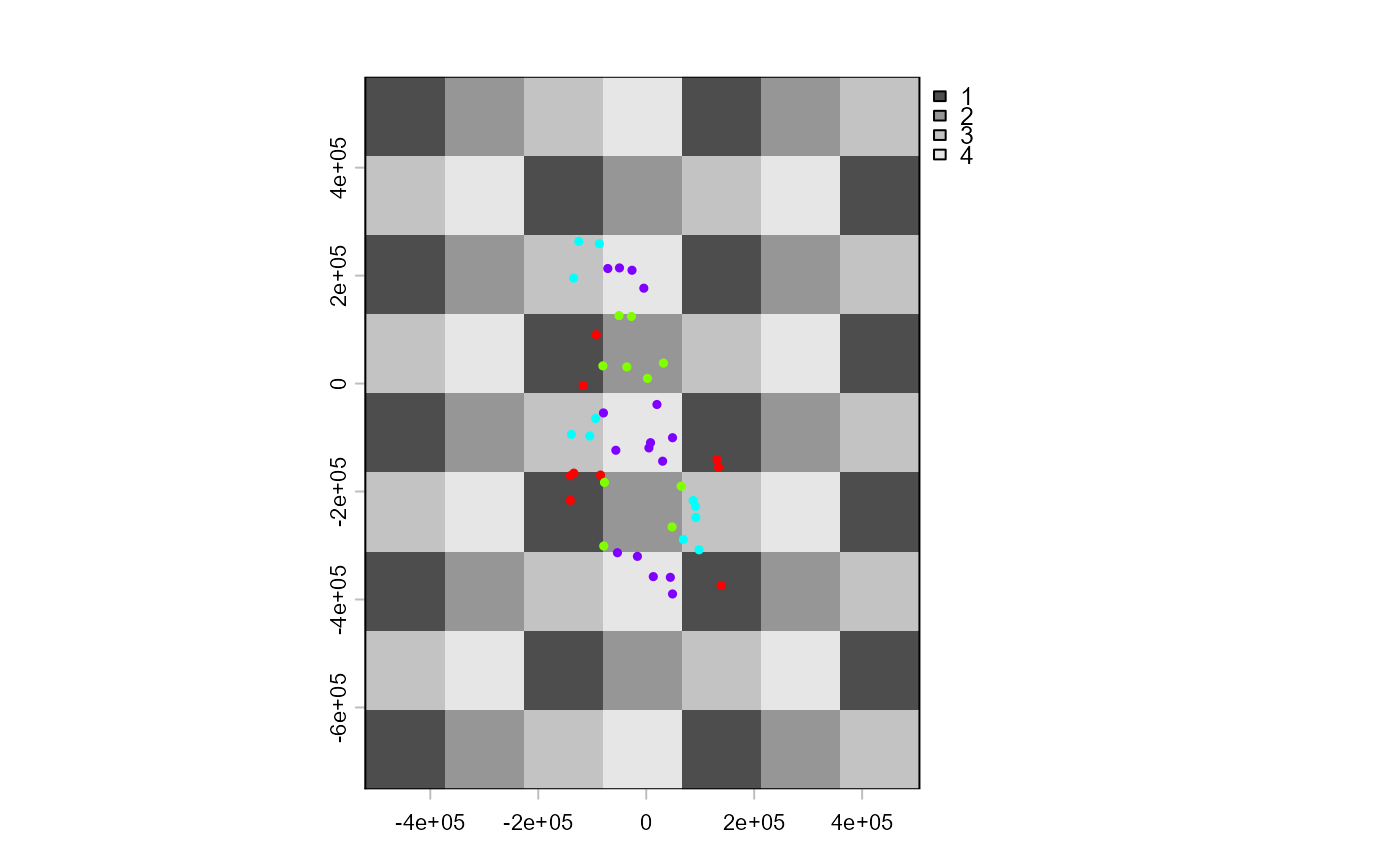
# Example of a higher number of partitions
part <- part_sblock(
env_layer = somevar,
data = single_spp,
x = "x",
y = "y",
pr_ab = "pr_ab",
min_res_mult = 10,
max_res_mult = 500,
num_grids = 30,
n_part = 4,
min_occ = 2,
prop = 0.5
)
#> 4 rows were excluded from database because NAs were found
#> The following grid cell sizes will be tested:
#> 18900 | 50834.48 | 82768.97 | 114703.45 | 146637.93 | 178572.41 | 210506.9 | 242441.38 | 274375.86 | 306310.34 | 338244.83 | 370179.31 | 402113.79 | 434048.28 | 465982.76 | 497917.24 | 529851.72 | 561786.21 | 593720.69 | 625655.17 | 657589.66 | 689524.14 | 721458.62 | 753393.1 | 785327.59 | 817262.07 | 849196.55 | 881131.03 | 913065.52 | 945000
#> Creating basic raster mask...
#> Searching for the optimal grid size...
# Explore the Grid object
plot(part$grid, col = gray.colors(4))
points(part$part[c("x", "y")],
col = rainbow(n = 4)[part$part$.part],
cex = 0.5,
pch = 19
)
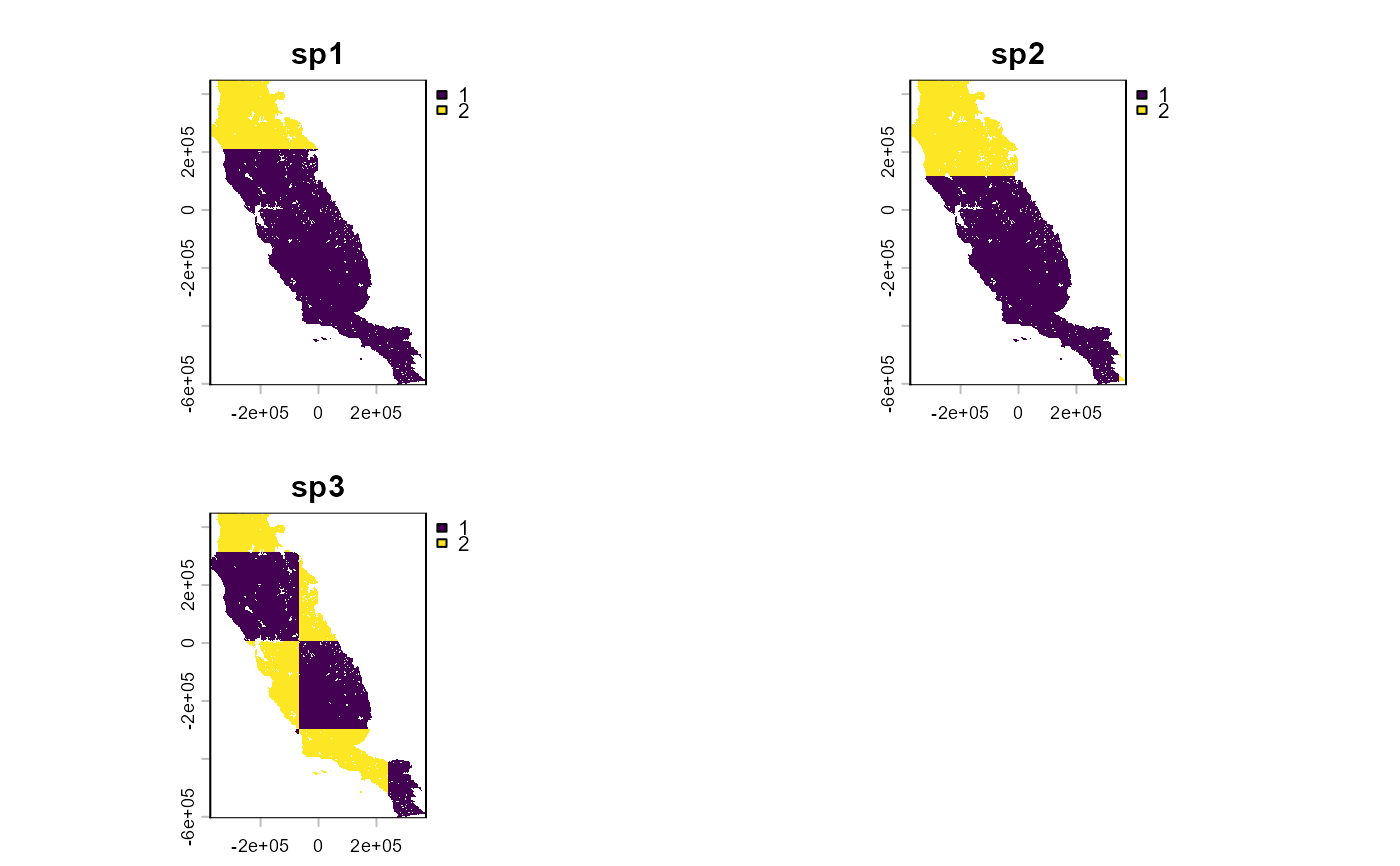
 # Using these functions with several species
spp2 <- split(spp, spp$species)
class(spp2)
#> [1] "list"
length(spp2)
#> [1] 3
names(spp2)
#> [1] "sp1" "sp2" "sp3"
part_list <- lapply(spp2, function(x) {
result <- part_sblock(
env_layer = somevar,
data = x,
x = "x",
y = "y",
pr_ab = "pr_ab",
min_res_mult = 10,
max_res_mult = 500,
num_grids = 30,
n_part = 2,
min_occ = 5,
prop = 0.5
)
result
})
#> 55 rows were excluded from database because NAs were found
#> The following grid cell sizes will be tested:
#> 18900 | 50834.48 | 82768.97 | 114703.45 | 146637.93 | 178572.41 | 210506.9 | 242441.38 | 274375.86 | 306310.34 | 338244.83 | 370179.31 | 402113.79 | 434048.28 | 465982.76 | 497917.24 | 529851.72 | 561786.21 | 593720.69 | 625655.17 | 657589.66 | 689524.14 | 721458.62 | 753393.1 | 785327.59 | 817262.07 | 849196.55 | 881131.03 | 913065.52 | 945000
#> Creating basic raster mask...
#> Searching for the optimal grid size...
#> 6 rows were excluded from database because NAs were found
#> The following grid cell sizes will be tested:
#> 18900 | 50834.48 | 82768.97 | 114703.45 | 146637.93 | 178572.41 | 210506.9 | 242441.38 | 274375.86 | 306310.34 | 338244.83 | 370179.31 | 402113.79 | 434048.28 | 465982.76 | 497917.24 | 529851.72 | 561786.21 | 593720.69 | 625655.17 | 657589.66 | 689524.14 | 721458.62 | 753393.1 | 785327.59 | 817262.07 | 849196.55 | 881131.03 | 913065.52 | 945000
#> Creating basic raster mask...
#> Searching for the optimal grid size...
#> 4 rows were excluded from database because NAs were found
#> The following grid cell sizes will be tested:
#> 18900 | 50834.48 | 82768.97 | 114703.45 | 146637.93 | 178572.41 | 210506.9 | 242441.38 | 274375.86 | 306310.34 | 338244.83 | 370179.31 | 402113.79 | 434048.28 | 465982.76 | 497917.24 | 529851.72 | 561786.21 | 593720.69 | 625655.17 | 657589.66 | 689524.14 | 721458.62 | 753393.1 | 785327.59 | 817262.07 | 849196.55 | 881131.03 | 913065.52 | 945000
#> Creating basic raster mask...
#> Searching for the optimal grid size...
part_list$sp3 # For this dataset a suitable partition was not found
#> $part
#> # A tibble: 46 × 4
#> x y pr_ab .part
#> <dbl> <dbl> <dbl> <int>
#> 1 -26331. 209912. 1 2
#> 2 -134331. 195332. 1 1
#> 3 68709. -288778. 0 1
#> 4 -79251. -54418. 0 2
#> 5 97869. -307948. 0 2
#> 6 4989. -119218. 0 1
#> 7 30369. -143788. 0 1
#> 8 91929. -248008. 0 1
#> 9 -80331. 32792. 0 1
#> 10 131079. -140548. 1 1
#> # ℹ 36 more rows
#>
#> $best_part_info
#> # A tibble: 1 × 6
#> n_grid cell_size spa_auto env_sim sd_p sd_a
#> <int> <dbl> <dbl> <dbl> <dbl> <dbl>
#> 1 5 306310. 0.35 361. 0 2.83
#>
#> $grid
#> class : SpatRaster
#> size : 5, 4, 1 (nrow, ncol, nlyr)
#> resolution : 306310.3, 306310.3 (x, y)
#> extent : -679996.2, 545245.2, -911123.7, 620428 (xmin, xmax, ymin, ymax)
#> coord. ref. : +proj=aea +lat_0=0 +lon_0=-120 +lat_1=34 +lat_2=40.5 +x_0=0 +y_0=-4000000 +datum=NAD83 +units=m +no_defs
#> source(s) : memory
#> name : .part
#> min value : 1
#> max value : 2
#>
# Create a single database for all species
occ_part <- lapply(part_list, function(x) {
if (!length(x) > 0) {
x[[1]]
}
}) %>%
dplyr::bind_rows(.id = "species")
occ_part
#> # A tibble: 0 × 0
# Get the best grid info for all species
grid_info <- dplyr::bind_rows(lapply(
part_list,
function(x) x[[2]]
), .id = "species")
# Get the best grid layer for all species
grid_layer <- lapply(part_list, function(x) x$grid)
grid_layer2 <-
lapply(grid_layer, function(x) {
get_block(env_layer = somevar[[1]], best_grid = x)
})
grid_layer2 <- terra::rast(grid_layer2)
grid_layer2
#> class : SpatRaster
#> size : 558, 394, 3 (nrow, ncol, nlyr)
#> resolution : 1890, 1890 (x, y)
#> extent : -373685.8, 370974.2, -604813.3, 449806.7 (xmin, xmax, ymin, ymax)
#> coord. ref. : +proj=aea +lat_0=0 +lon_0=-120 +lat_1=34 +lat_2=40.5 +x_0=0 +y_0=-4000000 +datum=NAD83 +units=m +no_defs
#> source(s) : memory
#> varnames : somevar
#> somevar
#> somevar
#> names : sp1, sp2, sp3
#> min values : 1, 1, 1
#> max values : 2, 2, 2
plot(grid_layer2)
 # Block partition for presences-only database
single_spp <- spp %>%
dplyr::filter(species == "sp1", pr_ab == 1)
single_spp
#> # A tibble: 250 × 4
#> species x y pr_ab
#> <chr> <dbl> <dbl> <dbl>
#> 1 sp1 -269871. 69512. 1
#> 2 sp1 -149991. 267962. 1
#> 3 sp1 -126231. 196142. 1
#> 4 sp1 91659. -156748. 1
#> 5 sp1 -210471. 326282. 1
#> 6 sp1 -140541. 284972. 1
#> 7 sp1 -217491. 65732. 1
#> 8 sp1 -201831. 17132. 1
#> 9 sp1 -40101. 150782. 1
#> 10 sp1 -178611. 225032. 1
#> # ℹ 240 more rows
single_spp$pr_ab %>% unique() # only presences
#> [1] 1
part <- part_sblock(
env_layer = somevar,
data = single_spp,
x = "x",
y = "y",
pr_ab = "pr_ab",
min_res_mult = 10,
max_res_mult = 500,
num_grids = 30,
n_part = 4,
min_occ = 10,
prop = 0.5
)
#> 12 rows were excluded from database because NAs were found
#> The following grid cell sizes will be tested:
#> 18900 | 50834.48 | 82768.97 | 114703.45 | 146637.93 | 178572.41 | 210506.9 | 242441.38 | 274375.86 | 306310.34 | 338244.83 | 370179.31 | 402113.79 | 434048.28 | 465982.76 | 497917.24 | 529851.72 | 561786.21 | 593720.69 | 625655.17 | 657589.66 | 689524.14 | 721458.62 | 753393.1 | 785327.59 | 817262.07 | 849196.55 | 881131.03 | 913065.52 | 945000
#> Creating basic raster mask...
#> Searching for the optimal grid size...
part$part %>% dim()
#> [1] 238 4
part$best_part_info
#> # A tibble: 1 × 5
#> n_grid cell_size spa_auto env_sim sd_p
#> <int> <dbl> <dbl> <dbl> <dbl>
#> 1 10 306310. 0.47 299. 52.1
part$grid
#> class : SpatRaster
#> size : 5, 4, 1 (nrow, ncol, nlyr)
#> resolution : 306310.3, 306310.3 (x, y)
#> extent : -679996.2, 545245.2, -911123.7, 620428 (xmin, xmax, ymin, ymax)
#> coord. ref. : +proj=aea +lat_0=0 +lon_0=-120 +lat_1=34 +lat_2=40.5 +x_0=0 +y_0=-4000000 +datum=NAD83 +units=m +no_defs
#> source(s) : memory
#> name : .part
#> min value : 1
#> max value : 4
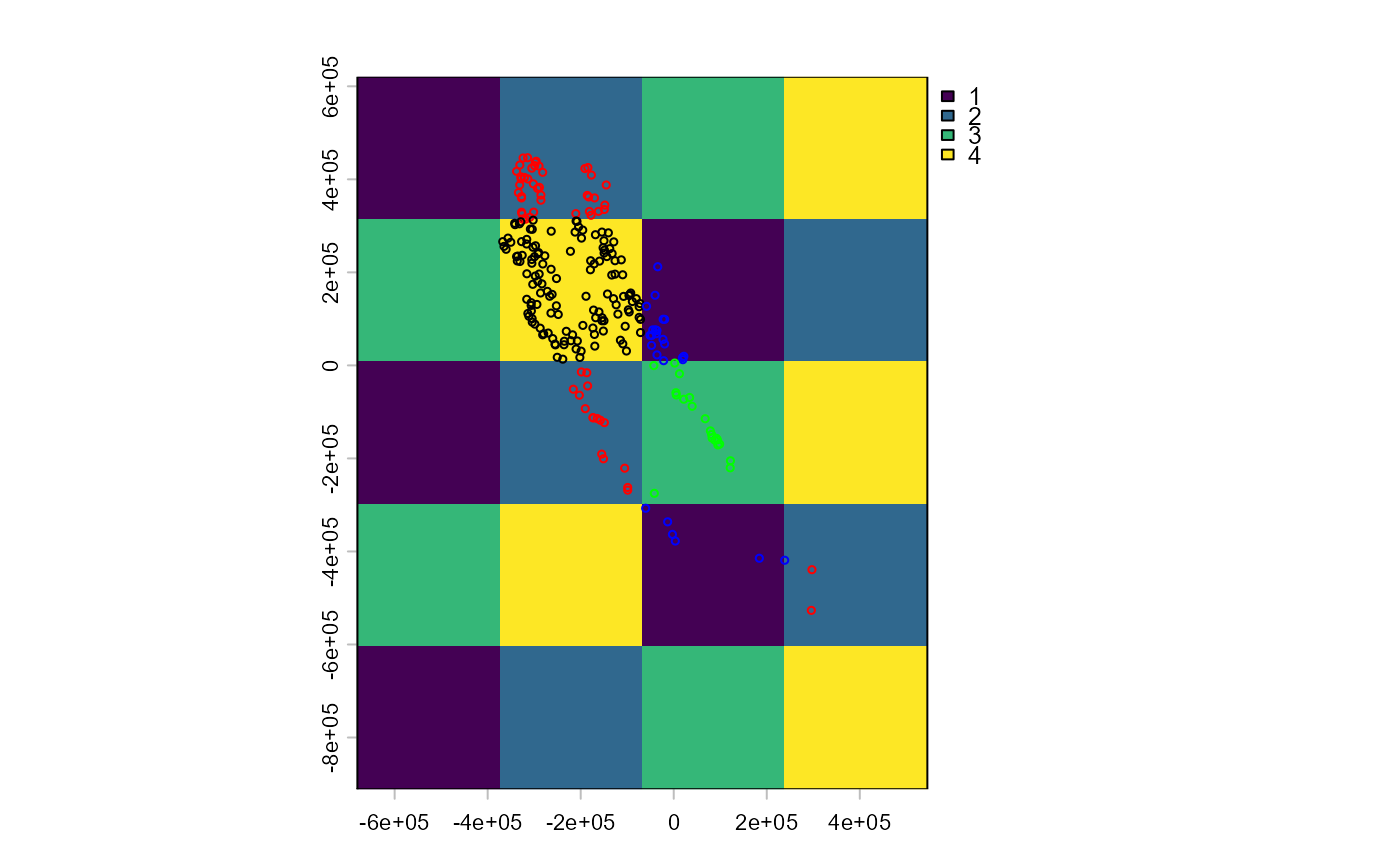
plot(part$grid)
points(
part$part[c("x", "y")],
col = c("blue", "red", "green", "black")[part$part$.part],
cex = 0.5,
#' pch = 19
)
 # }